• 6 Posts
  • 121 Comments
Joined 8 months ago
cake
Cake day: January 9th, 2026

help-circle

  • In KDE my favorite is an extension to the window manager, for auto tiling: https://codeberg.org/anametologin/Krohnkite or install it from Settings > Window Management > KWin Scripts, then click “Get New” and search for “Krohnkite” by anametologin. Development is a bit slow at the moment, but it does the job well.

    I like that there are different layouts available, meaning different logic how a window should be placed and sized. I can switch between layouts on the fly. Every virtual desktop can have their own layout by standard, in example my fourth desktop is always untiled like a normal desktop. Exceptions to specific windows or applications to not tile them can be added too. So the usual stuff. It comes with some features not seen in other tiling window managers. In example I can convert any window into a “Dock”. A dock would then be always at the edge or screen, similar to the KDE bar; basically making the screen area to tile windows smaller. Super cool.

    Edit: Rephrased a bit to make it more clear and added some more info.

  • This is where the server/client concept comes from. Some server software runs in the background and wait for access from an external client software. Then it works on the server and produces and output for the client. This way the entire server does not need to start run and stop for every single request. I mean you don’t start and close every time you click on a new link on the website, right? So your PC runs all the time. And that’s similar to how MySQL operates. It starts a server in the background and then waits for any application to use it. So this is totally normal.

    Now because lot of people don’t want to start the server process “by hand”, they put it in autostart, so it starts with your system. If you don’t want it to autostart, maybe there is a way of configuring it so you have to start it manually each time you want to use it. But I cannot assist with that help, just wanted to explain why that is on a high level.


  • While it was wrong move, it is a legit option. Such streams just displays what many people actually do, especially those not very technically versed. So I see more of an exposure of many, than a single personal mistake here, because this is not an issue in isolation. And its good that we see this on display, because we talk and point to it and others learn why that needs to be done. I’m not defending his mistake, just talk more broadly about the issue.

    We have seen ignoring warnings from other channels too… its more common than people think. I think people ignore this, because everything is overwhelming when new to Linux. They learn so much, experiment so much, its just like in Tokyo all lights blend you and then you just click off… ok… at this point I maybe defended his mistake. :D Goddammit I’m too optimistic!


  • I exclusively use EXT4, so this is welcome improvements. It’s really rock solid and performance is good too. Not sure how relevant these improvements other than measuring them in specific cases will be for my daily usage, but it can’t hurt I guess. Article also talks about:

    avoiding possible soft lockups or RCU stall conditions, and a variety of bug fixes

    Which is impressive, because its pretty darn good already. I wonder if anyone ecountered a bug in the filesystem on a live system in recent years or if this is just some cleanups they found when inspecting the code, without affecting anyone in real world?


  • What makes this Chatbot client different from just using it in the browser? My first thought was, it might get special permission to better interact with the system, like the agentic tools do. I assume it can better integrate into system with the taskbar maybe. Or maybe this is more efficient than just running the webbrowser. Or it might have special commandline arguments with special options?

    Oh… wait its just an entire browser running a single tab. Alright then. Why does this need to be an app on its own? To me this is as useless as a native browser based Discord app… Just bookmark it in your browser and open it there. You can even customize it even more with browser addons.


  • Ah! I’ve seen a few times some artifacts with my RX 7600 on KDE too, but not on max/min, but randomly. I couldn’t reproduce it, so it is really hard to talk about such subject. As it just recently started (I’m on 7.1.6), I guess this is the same issue. Wondered if this is an issue with KDE or Krohnkite extension or my GPU dying.

    So glad it’s “just” a bug in the Kernel. This is just a visual issue right? It doesn’t hurt I hope.


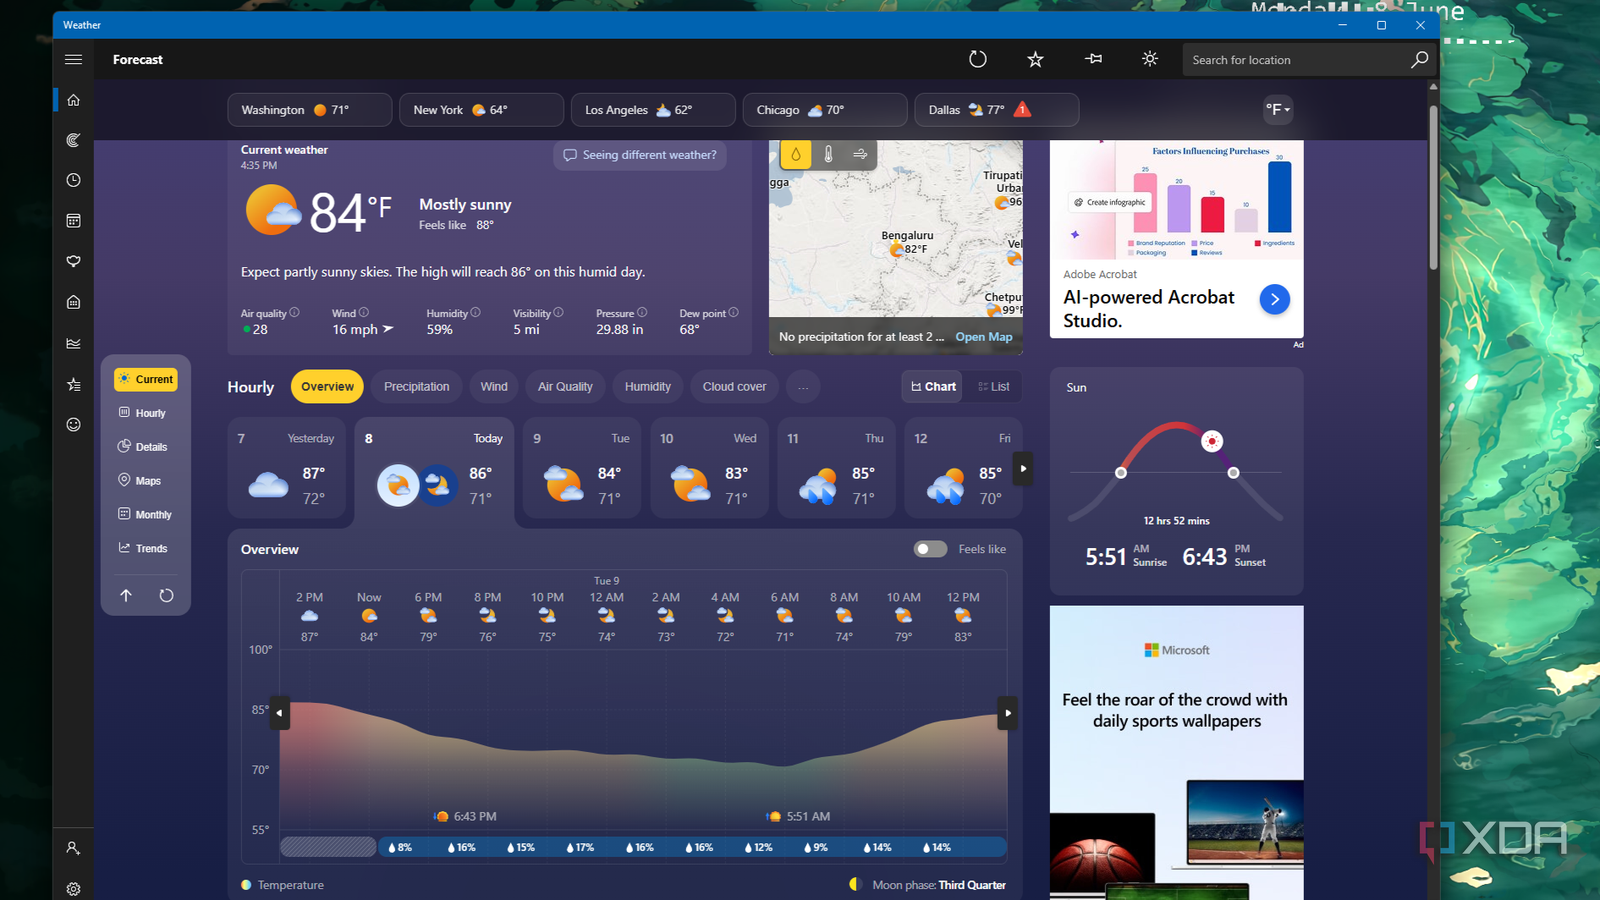
  • I think reading how much RAM a program uses is a bit complicated. In example there are shared libraries, and RAM will be reused if multiple applications uses the same resource. If two programs using the same library uses up 1.2gb on their own, then starting up app A and measure its 1.2gb, then close and measure app B with 1.2gb would give you exactly that. But in reality if both apps would run at the same time, their total RAM usage might be just 1.4gb.

    As an example, if I already run KDE on my system and another KDE app starts up, it might not use too much more RAM. But the same app on a GNOME system might require a lot of additional RAM. So the Windows 11 Weather app might not even use 1.2gb on its own. No idea how they measured it.


  • If a company unethically steals data and publishes a book with that data, we don’t say that there are legitimate concerns using books.

    Off course we say its a legitimate concern if someone unethically steals data and publishes a book with that data… The point of scraping and stealing data without respecting its license, training their software with it and using it commercially (or even non commercially) without giving even credit and not respecting its original license?

    the problem that people … have with AI isn’t with the technology itself nor its use, but the methods by which the companies “grow and harvest it”, so to speak.

    No, its not just the methods. I am talking about deep problems with the technology, the methods how companies go with it, and then its usage from company and end user. Ai trained with those data and used makes it impossible to respect the original license, for the user. So in this case, the company using the Ai AND the user of the model violate licenses. Maybe. Maybe not, if the data allows it. But we don’t know and CANNOT check and know for sure, that’s the problem. Just because you don’t understand the issue or don’t care does not make it less of a problem.

    As an example with software licenses like GPL requires that any derivative works using this source code (such as Linux or whatever my personal program is licensed under GPL) has to be GPL licenses (Open Source) too. That is not debatable. That is how this license work. Now the Ai can be trained on this data, using the source code, and then? See where this goes? That is only one generalized example.


  • You’re problem with AI isn’t with the technology itself nor its use.

    I’m not sure about the weed argument, can’t say anything about it. But first, my personal problem with Ai doesn’t matter to this disussion, as I was talking about what people could have an issue with, not about my personal problems. Secondly farming data without respecting the original license, not even linking to the source where it got from is in fact a problem with “its use”. That is an unsolved problem lot of people just ignore, which does not make it less of a problem (it makes it a bigger problem). And that is just a few issues I listed, not even talking about the problems of generated content. There are legitimate concerns using Ai, no matter how you frame it, some just choose to ignore it.